AI
Scientists and Auditors Still Decide If Lab AI Ships
Production lab AI stalls until veteran scientists, IT, and auditors can inspect the count, the model version, and the data map behind it.

Production-ready AI in a lab still needs a named scientist, an audit trail, and a data map written before any model is trained. James Smagala, bioinformatics practice manager at Yahara Software in Madison, Wisconsin, has been walking lab managers through that gap: decades of LIMS records, instrument files, and nested Excel sheets on one side, and a model someone wants to put on a report on the other.
The people who decide whether that model ships are not the champion who got a clean demo to work. They are the veteran who will not sign a count they cannot inspect, the IT and security teams who will not let personal API keys into production, and the auditor who will ask how a result was made.
Spreadsheets Still Hold the Lab’s Memory
Vendor pitches in September 2026 still open with notebooks and spreadsheets, because that is still where a lot of results live. Manual entry in those files is a data-integrity problem as well as a cleanup problem. In a regulated lab, the electronic record has to be trustworthy, secure, and reconstructable.
That pile raises a chicken-or-egg fight. Do you spend months, or years, rebuilding the architecture first, or do you point a model at the mess and let it sort folders? Smagala’s answer is neither extreme. A lab cannot dump raw chaos into a model and wait for magic. Perfect architecture is also not a gate that has to close before anyone starts.
“You need a little bit of organization and architecture in place first,” he said. The missing piece is a view of the finished state: standard taxonomies, schemas, and data rules. ISO/IEC 17025:2017, the competence standard for testing and calibration labs, already treats method validation and control of data as core duties. Without a map of how records should be categorized, there is nothing coherent to train on.
Once that map exists, he said, an “AI cleaning crew” can iterate, tidy files, and park them in a longer-term repository. The crew does not invent the map. Labs that skip the map buy a faster way to encode the same disorder.
The Scientist Who Will Not Sign a Black Box
The cultural block is older than the current model wave. Scientists who have spent decades on a domain look at a neural net and see matrix math with no chemistry in it. Smagala does not wave that off.
A completely untuned model or a completely untuned AI may not really be respecting the biological nuances, and I think that a lot of the skeptical ‘I-want-it-to-work-a-certain-way’ crowd, has a point in being concerned about that.
James Smagala, bioinformatics practice manager, Yahara Software
Trust here is not a town hall. It is a workflow in which the veteran is the editor, not the audience. That is the human-in-the-loop bar, and it is also how high-risk systems are supposed to run in Europe. The EU AI Act, Regulation (EU) 2024/1689, puts high-risk AI human oversight rules on the provider and the deployer: a natural person has to be able to monitor the system, override it, and halt it, including with a stop control that leaves it in a safe state. Not every lab model will fall in that high-risk annex. The design still matches what a signing scientist already demands.
GUARDRAILS A SIGNING SCIENTIST CAN SEE
- Hard rules in the pipe: Biological limits, standard molecular structures, and thermodynamic bounds are written into preprocessing so the model cannot casually invent a forbidden state.
- The veteran as editor: Review loops send output to the domain expert, who can accept, reject, or send it back before it becomes a record.
- Final approval stays human: The model does the repetitive grind; the named scientist keeps the signature that goes on the result.
Set-it-and-forget-it tools fail this test on purpose. They optimize for a champion’s laptop, not for the person whose name is on the assay.
A Two-Tier Pipeline for FISH Counts
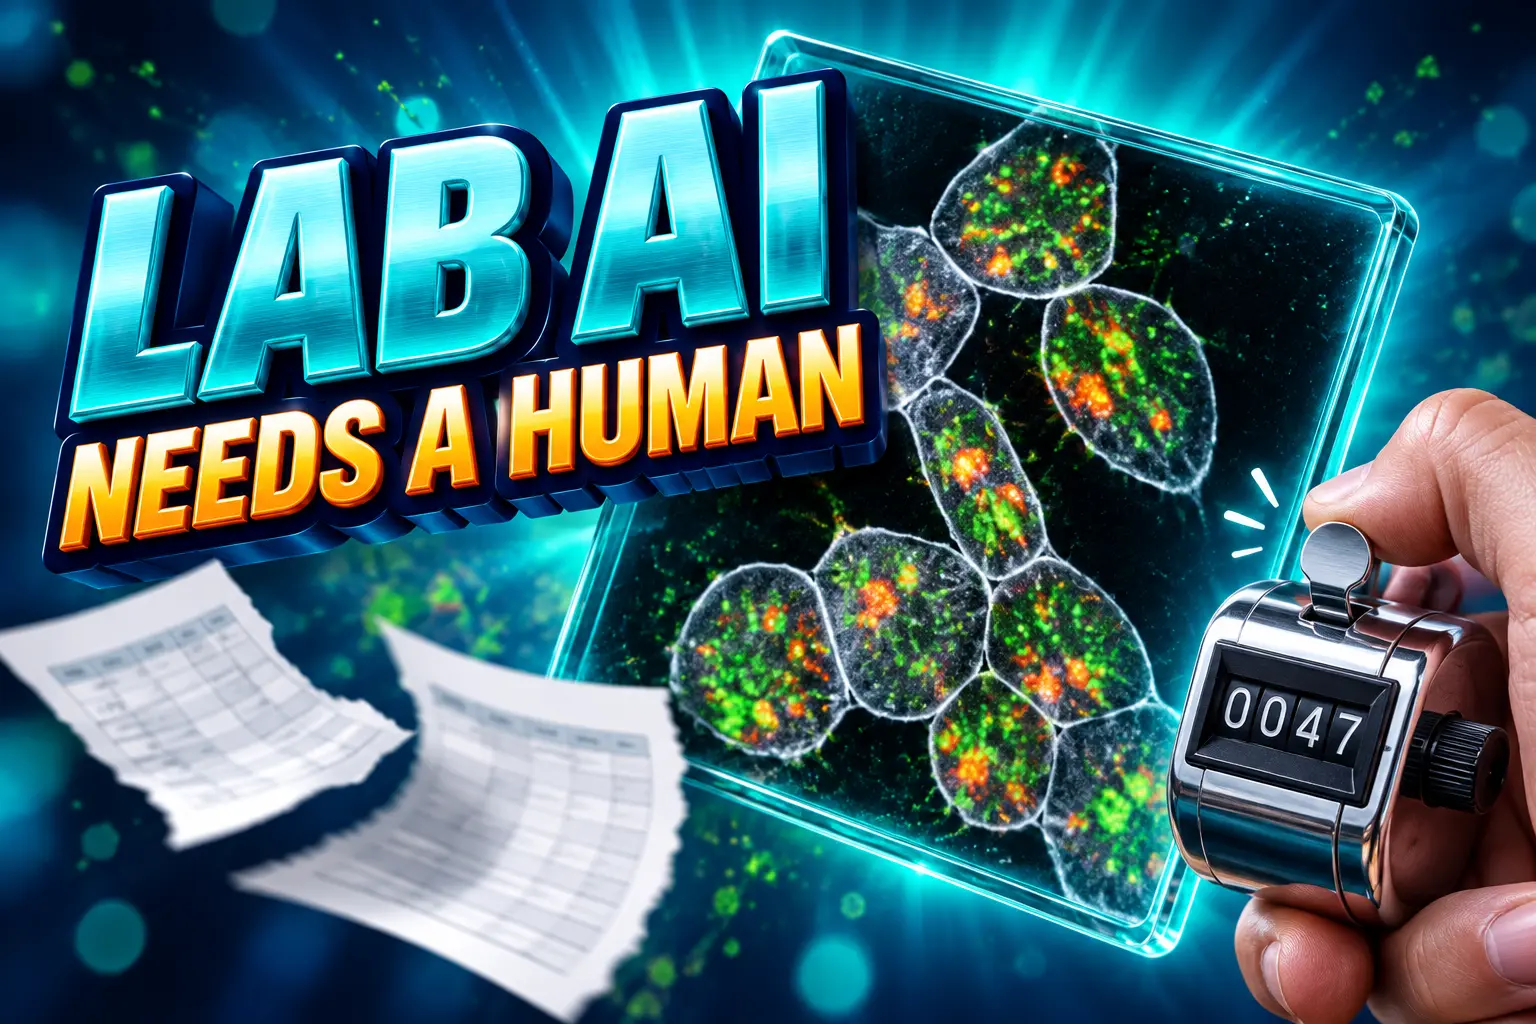
Smagala’s working example is a hybrid pipeline Yahara built with human oncology researchers at the University of Wisconsin-Madison. Fluorescence in situ hybridization, FISH, is the assay. Graduate students used to spend hours tracing cell outlines and counting chromosomes by eye, a grind that drifts with fatigue and with who is holding the mouse.
The team split the job. Cell boundaries came from MicroSAM, also written µSAM, a microscopy-tuned version of Meta’s Segment Anything Model. The Segment Anything for Microscopy paper in Nature Methods, volume 22, pages 579 to 591, was published on February 12, 2025 by Anwai Archit, Constantin Pape, and colleagues at the University of Göttingen. They fine-tuned generalist models for light and electron microscopy on over 17,000 microscopy images with over 2 million structures annotated by hand, then shipped a napari plugin for interactive and automatic work. Because that generalist already knew how to find an object, the Madison group did not have to hand-label a huge private set just to get outlines.
Counting did not stay in the net. Once the outline existed, the pipeline left machine learning and used a classical bright-spot detector on the fluorescent signals inside the cell. If someone challenges the number, a developer or a scientist can open the detector’s settings.
THE TWO-TIER FISH PIPELINE
| Tier | Job | What runs it | Why a skeptic can inspect it |
|---|---|---|---|
| 1. Outlines | Find cell boundaries | MicroSAM (µSAM) | A published generalist model, used so the lab does not start from a blank label set |
| 2. The count | Tally fluorescent spots inside those boundaries | Deterministic bright-spot detection | The math and parameters can be opened, checked, and replayed |
Smagala’s production test is blunt. “It is returning what you expect at a higher correctness rate and a higher consistency rate than most humans can do it,” he said. “And now you are ready to use that model in a production context. Until that point, your skeptic is right to be skeptical.” The model that ships is the one that knows where to stop.
Machine Learning Wants Cleaner Data Than a Chatbot
Cleanup has to match the job, which is why “we did some AI on the archive” is not a status. Classic machine learning for predictive analytics or automated assay design is picky about bias and noise. “It’s absolutely crucial to do the upfront data organization before you launch into the full AI implementation or machine learning implementation,” Smagala said. “Those are heavily dependent on starting with the right data and data of a certain quality.”
That bar is the same one regulators keep repeating for clinical algorithms. The U.S. Food and Drug Administration’s AI and machine learning medical device plan, released on January 12, 2021, and the Good Machine Learning Practice principles that followed in October 2021, both press on representative, well-characterized data and on methods to evaluate models over their life. A lab that wants a predictor, then feeds it the shared drive, is not close.
Generative tools sit on a lower structural rung. If the aim is to query SOPs or old reports with a large language model or retrieval-augmented generation, the files can be less rigidly typed. The model can parse messy prose. It still needs an organizational frame, or the answers will be fluent and unmoored. The split is practical: chat can live with uglier text; a predictor cannot.
Why Most Lab AI Pilots Never Leave the Demo
A pilot is easy to make look good. One scientist, one curated set, one quiet room, and the plot will pop. Smagala said the vast majority of those lab pilots then fail when they meet volume. He watches for two tells.
The first is infrastructure. Pilots often run on personal access keys to an API, against a hand-picked static file. “Those pieces of infrastructure that go around a full-scale production use require you to have a full build-out plan and usually support from multiple teams across your enterprise organization,” he said. IT, DevOps, cybersecurity, and data engineering have to be in the room before the first line of pilot code, not after a screenshot goes to leadership. Cross-functional gaps are a large part of why most lab AI pilots fail once the demo has to live on shared systems.
Bench staff pay for that late scramble. New tools stacked on old LIMS work without a build-out plan produce change fatigue in the people still generating the data. Operations leads who want the line to keep moving have to keep that load off the bench, which only works if the other teams were already staffed into the project.
The second tell is the happy path. Developers prove value on one or two clean cases. No noisy inputs, no broken files, no edge cases. “If you don’t have a rich enough and robust enough program around how the data is going to interact once you scale this up, you will fail,” Smagala said. Treat the pilot like an experiment: validation protocols, quality checkpoints, and a plan to sample ugly data before anyone calls it production.
Audit Trails That Name the Model Version
This is not a future code of conduct. The record rules are already in force, and they care about who did what to a result, not about how impressive the demo looked.
21 CFR Part 11 is the FDA’s electronic records and electronic signatures rule. The agency issued it in March 1997 and it took effect on August 20, 1997. The September 2003 Part 11 electronic records scope guidance still describes how the agency reads it. Part 11 applies to records in electronic form that are created, modified, maintained, archived, retrieved, or transmitted under other FDA record rules, the predicate rules. The 2003 guidance narrows scope and holds back some enforcement on validation, audit trails, copying, and retention, and on systems that were already running before August 20, 1997. It still says Part 11 remains in effect. Access limits, operational and authority checks, training of the people who run the system, controls over system documentation, and electronic-signature rules are on the list the agency said it intends to enforce. Predicate-rule records still have to stay secure and reliable.
For a lab model, that is a design brief. If the output becomes a required electronic record, someone has to be able to reconstruct it. Yahara’s own public pitch for its AI work is “a solution you can defend to auditors,” and the CellX Technologies project it cites builds a step-by-step record of every experiment next to the vision and scheduling stack. A log that says only “AI processed result” does not do that job.
THE DATES ALREADY ON THE BOOKS
- August 20, 1997: 21 CFR Part 11 takes effect for electronic records and signatures in FDA-regulated work.
- September 2003: FDA issues the Part 11 scope and application guidance that labs still work from.
- January 12, 2021: FDA releases the AI/ML Software as a Medical Device Action Plan.
- October 2021: FDA, Health Canada, and the UK MHRA publish Good Machine Learning Practice guiding principles.
- December 2024: FDA issues final guidance on predetermined change control plans for AI-enabled device software.
- January 6, 2025: FDA publishes draft lifecycle and marketing-submission recommendations for AI-enabled devices, including bias and transparency.
- August 2, 2026: EU AI Act Article 50 transparency duties for certain systems begin to apply.
- December 2, 2027: High-risk AI duties in the EU, including dataset quality, logging, documentation, and human oversight, are scheduled to bind Annex III systems.
ISO/IEC 17025:2017 sits beside that stack for accredited testing and calibration labs. It does not name neural nets. It does require validated methods and control of the data and information used to produce a result. A model that writes into that result inherits the same burden. Predetermined change control plans, finalized in December 2024 for AI-enabled devices, exist because a learning system that quietly retrains is a change-control problem. Labs that treat a weights file like a spreadsheet macro will meet that problem the hard way. The next hard date on the European side is December 2, 2027.
Five Steps That Map to People, Not Tools
Smagala’s roadmap reads like a purchasing order if you squint. Read as an org chart, it names who has to be in the room.
WHO OWNS EACH STEP
- Data architecture blueprint: Lab leadership and informatics set the taxonomy, schemas, and finished-state map before anyone buys a tool.
- Targeted cleanup: Data stewards run basic models against that map to clean, categorize, and archive legacy sheets, then store the result where the map says it belongs.
- Human-in-the-loop validation: Veteran scientists sit as reviewers; their rules and vetoes are built into the workflow, not added in a training slide.
- Cross-functional alignment: IT, data engineering, security, and compliance join during the pilot, while the code is still small enough to change.
- Edge-case stress testing: Quality treats the pilot as an experiment and samples the ugly files that a demo never sees, so volume does not become the first real test.
Smagala came into Yahara when the firm acquired Revolutionary Informatics, the Golden, Colorado company he founded in 2018, on November 8, 2023. Yahara’s lab-informatics work goes back to Madison roots in 1994, when it operated as Tara Software. The hybrid FISH pipeline is the method that company is willing to put next to a signing scientist. Foundation models draw the messy outline. Classical math emits the number. A person still signs.
Until a developer can open the spot-detection settings and a scientist can overrule the call, the lab is not ready to run the model for real.

Lunit Turns Routine H&E Slides Into a Lung Pre-Screen

Meta’s Muse Agent Wants Your Inbox and Your Card

Police Chase Mules as AI Chatbots Run Romance Scams

ChatGPT Mil and Grok Take the Desk Anthropic Lost

Chewy Turns Vet Clinics Into the New Pet Aisle

Fable 5 Came Back Under a Commerce On-Off Switch

Google’s SpaceX GPU Lease Has a Sept. 30 Deadline

Plasma One’s XPL Locks Face a 1.81 Billion Cliff

DGO’s Rs 549 World Cup Pass Cost Fans Sleep and Data

Moonshot AI’s $30 Billion Ask Became a $35 Billion Close
-
 AI3 months ago
Fable 5 Came Back Under a Commerce On-Off Switch
-
 AI3 months ago
Google’s SpaceX GPU Lease Has a Sept. 30 Deadline
-
 CRYPTO3 months ago
Plasma One’s XPL Locks Face a 1.81 Billion Cliff
-
 APPS3 months ago
DGO’s Rs 549 World Cup Pass Cost Fans Sleep and Data
-
 AI3 months ago
Moonshot AI’s $30 Billion Ask Became a $35 Billion Close
-
 NEWS3 months ago
ColorOS 17 Device List Spans Oppo, OnePlus and Realme
-
 GAMING3 months ago
Xbox Cuts 3,200 Jobs After Five Years of Thin Returns
-
 GAMING3 months ago
The RTX 4050 Under Rs 70,000 Hides a Wattage Gap